
Active Correction Strategies for the Systematically Underweighted Memory Weight in AI Compute Indices
Most AI compute indicators and ETFs are built around the obvious heroes: GPUs, accelerators, and custom AI chips. Memory—the bandwidth and capacity that feed those chips—often shows up as a supporting cast with smaller index weights. That systematic underweighting of memory in AI compute indicators is understandable from a market-cap and narrative perspective, but it is increasingly at odds with how AI infrastructure actually works. If memory is a bottleneck, underweighting it is not just a technical quirk; it is a structural allocation error.
Active correction strategies are about fixing that error. They do not mean abandoning AI compute exposure. They mean deliberately adding, tilting, or overlaying memory exposure so that your AI hardware portfolio matches the physical reality of the stack more closely. This post walks through practical ways to do that using ETFs and index derivatives on AI storage and computing power.
Why Memory Is Systematically Underweighted
To correct a problem, you need to understand its roots. AI compute indicators tend to underweight memory for several reasons:
- Market-cap bias: GPU and accelerator designers often have larger market caps than pure memory makers, so cap-weighted indices skew toward compute.
- Narrative bias: Compute is seen as the exciting part of AI—FLOPS, model counts, benchmarks. Memory is perceived as “just infrastructure,” even when it is the constraint.
- Legacy sector definitions: Many AI indices evolved from traditional semi benchmarks that already favored logic over memory.
The result is systematic underrepresentation of memory in AI hardware exposure. AI compute indicators can look like balanced representations of AI infrastructure while, in practice, giving far less weight to DRAM, HBM, and related storage components than AI workloads actually depend on. Active correction strategies aim to restore balance.
Why Underweighting Memory Matters in AI
Modern AI training and inference stress not only compute but also memory bandwidth, latency, and capacity. KV caches, activation maps, and model states need to live somewhere close to the processors. Without sufficient memory, you cannot keep GPUs fully utilized. The so‑called “memory wall” is often what slows down AI deployments, not lack of raw FLOPS.
Underweighting memory in AI compute indicators matters because:
- Risk is mispriced: You carry more risk in compute names than in memory names, even though memory constraints can hurt overall infrastructure.
- Return drivers are misaligned: You may miss upside in memory when memory pricing and HBM demand surge alongside compute capex.
- Hedge effectiveness is reduced: Memory and compute are tightly correlated in AI, so ignoring memory distorts hedging strategies.
Active correction is therefore about aligning your AI hardware exposure with the actual risk-return drivers of AI deployment, not just with the headlines.
Strategy 1: Memory Overlay on Top of AI Compute ETFs
The simplest correction strategy is to overlay memory exposure on top of existing AI compute ETF positions. If your core AI hardware allocation is in compute-heavy ETFs, you can add a dedicated memory ETF or index derivative to raise the effective memory weight.
A practical approach:
- Estimate the current memory weight in your AI compute ETFs (often low single-digit to low double-digit percentages).
- Define a target memory weight that better reflects AI storage importance (for example, 25–40% of your AI hardware sleeve).
- Overlay memory exposure via a memory ETF or memory index futures/options to reach that target.
For instance, if you have a $100,000 AI compute ETF position and memory is only 10% of its benchmark, you could add $20,000–$30,000 in a memory ETF to raise the aggregate memory share. This overlay keeps your compute exposure intact while actively adjusting the theme’s internal balance.
The advantage of this approach is its simplicity. You do not need to redesign the index; you build a composite exposure using existing products.
Strategy 2: Dual-Sleeve AI Hardware Portfolio (Compute + Memory)
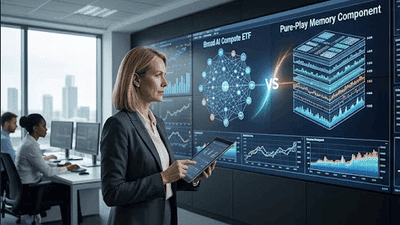
A more structured strategy is to treat AI hardware exposure as two explicit sleeves: AI compute and AI memory. Instead of relying on compute-heavy indicators and trying to guess memory’s share, you define a dual-sleeve architecture.
For example:
- Compute sleeve: AI compute ETFs and derivatives (GPUs, accelerators, logic).
- Memory sleeve: Memory/HBM ETFs and derivatives (DRAM, NAND, HBM, related suppliers).
- Target split: 60/40, 50/50, or other ratio based on your view of the bottlenecks.
You then allocate capital according to that split, rebalancing periodically. The result is a custom AI hardware index within your portfolio that explicitly corrects for memory underweighting. You are no longer dependent on the internal biases of compute-heavy benchmarks; you decide the memory share.
This approach is particularly attractive for long-term AI infrastructure investors who want a transparent and durable way to own the hardware stack.
Strategy 3: Factor-Tilted Reweighting of Existing AI Compute Indices
If you are constrained to a specific AI compute index, you can still correct memory underweighting by reweighting the index in a factor-tilted way within your own portfolio. This is effectively building your own smart beta overlay.
The idea:
- Hold the AI compute ETF as your base exposure.
- Identify memory-related constituents within that ETF (companies with significant DRAM/HBM segments).
- Tilt your allocation toward those names using single-stock positions or complementary ETFs, while underweighting non-memory names relative to the ETF.
For instance, you might add direct positions in major memory constituents of the compute ETF, while trimming exposure to purely logic-focused names or balancing with a general semi ETF. The net effect is a factor tilt toward memory within the AI compute benchmark.
This strategy is more complex and works best when you have a good understanding of constituent-level exposures. It is an active overlay against a passive benchmark, which may appeal to institutional or advanced retail investors.
Strategy 4: Use Index Derivatives for Tactical Memory Corrections
Index derivatives—futures and options on memory and AI hardware indices—are powerful tools for tactical correction. If you believe memory is systematically underweighted and is about to play a larger role in the next phase of AI deployment, you can use derivatives to quickly adjust exposure without rebalancing cash positions.
Examples:
- Buying memory index futures to increase memory exposure for a defined tactical window (e.g., ahead of expected HBM price hikes).
- Purchasing call options on memory ETFs while using AI compute ETF puts or collars to hedge downside risk.
- Implementing spread strategies between memory and compute indices when you expect memory to catch up or outperform.
These derivative-based corrections allow you to be more agile. They are best suited to tactical traders or risk managers who want to adjust memory weight quickly around events or cycle inflection points without fully restructuring underlying ETF holdings.
The trade-off is complexity and leverage; derivative overlays should be carefully sized and monitored.
Risk Management in Memory Corrections
Actively correcting memory underweighting introduces new risks. Memory is more cyclical and often more volatile than compute. Correcting underweighting does not eliminate that volatility; it intentionally brings more of it into your portfolio. Risk management must therefore be built into the correction strategy.
Key considerations:
- Position size limits: Cap memory exposure at a level appropriate for your risk tolerance (e.g., no more than 40–50% of your AI hardware sleeve).
- Cycle awareness: Recognize memory cycles—pricing upturns vs downturns—and adjust correction intensity accordingly.
- Drawdown thresholds: Set rules for reducing memory overlays if drawdowns exceed predefined levels.
- Hedging options: Use options or inverse products to protect against extreme memory shocks when necessary.
Correcting underweighting is not an excuse to ignore memory risk; it is a recognition that memory deserves more weight in your risk analysis. Active strategies must respect both the structural importance of memory and its cyclical nature.
When Correction Makes Sense (and When It Doesn’t)
Active correction strategies are most compelling when:
- AI storage demand is clearly tightening—e.g., repeated HBM shortages, rising DRAM contract prices.
- Memory capex is disciplined, reducing the risk of overbuild.
- AI deployments are scaling horizontally, increasing overall memory footprint.
In these conditions, underweighting memory is likely a liability; correcting it can add both resilience and upside. Correction is less compelling when:
- Memory supply is clearly ahead of demand.
- Pricing trends are negative and inventory issues persist.
- AI infrastructure spending is focused on compute expansions without commensurate memory upgrades.
In such cases, systematically underweighted memory may reflect real risk considerations, and correction should be cautious or delayed. Active strategies are about tuning exposure, not forcing symmetry regardless of fundamentals.
Integrating Memory Corrections Into a Broader AI Framework
Memory correction should be viewed within the context of a broader AI infrastructure allocation. You might have sleeves for compute, memory, equipment, and networking. Correcting memory underweighting is part of ensuring that the overall hardware stack is represented accurately.
A robust AI hardware allocation by 2027 might look like:
- Core: Broad AI hardware ETF capturing compute, memory, equipment, and networking.
- Correction: Memory overlay or dual-sleeve structure to increase memory share relative to compute-heavy indicators.
- Refinement: Tactical derivative overlays and factor tilts to respond to cycle changes.
In this holistic view, memory correction is not an isolated trade. It is part of making sure your AI hardware positioning mirrors the real constraints and drivers of AI deployment.
Conclusion
The systematic underweighting of memory in AI compute indicators is one of the subtle but important mismatches in today’s AI investing landscape. Memory—especially HBM and advanced DRAM—has become a core bottleneck and driver of AI infrastructure performance. Leaving it underrepresented is a structural misalignment between index design and technological reality.
Active correction strategies—memory overlays, dual-sleeve allocation, factor-tilted reweighting, and index derivative overlays—offer practical ways to fix that misalignment. They allow investors to keep their AI compute exposure while deliberately increasing memory representation to reflect its central role. The key is to do it thoughtfully, with an eye on cycles, volatility, and risk.
As AI storage and computing power continue to evolve, so must the way we build and adjust our hardware exposure. Correcting memory underweighting is not just a theme tweak; it is part of bringing AI investment frameworks in line with the actual physics and economics of AI infrastructure. That alignment is where smarter AI hardware portfolios will come from in the years ahead.
You May Like

Narrowing Spread Between NAND Spot and Contract Prices in 2026 – A Signal
By 2026, one of the most watched metrics in the NAND flash market has started to shift in a subtle but meaningful way: the spread between spot prices and long‑term contract prices is narrowing. For casual observers, this may look like just another incremental change in a notoriously volatile industry. For memory makers, module houses, device OEMs, and data center buyers, however, a tightening gap between spot and contract prices is a signal—a reflection of evolving supply–demand balance, risk perceptions, and strategic behavior on both sides of the market.

Price Divergence Trading Strategies Between NAND Flash and DRAM ETFs
NAND flash and DRAM sit at the core of AI storage and computing power. Both are memory, but they are not the same business. DRAM is main memory—fast, volatile, and central to high‑bandwidth workloads like AI training and inference. NAND is non‑volatile storage—slower than DRAM, but crucial to persistent data and large‑scale object storage. The cycles that drive their pricing and margins overlap, yet they often diverge. That divergence is where trading strategies between NAND and DRAM ETFs become interesting.

China’s HBM Localization Progress: The Catch-Up Pace of CXMT and XMC
China’s drive to localize advanced memory technologies has accelerated over the past several years. High-Bandwidth Memory (HBM) sits near the center of that strategy because it is integral to AI accelerators, high-performance computing (HPC) and other strategic compute platforms. Two domestic players—ChangXin Memory Technologies (CXMT) and XMC (Xianghui Memory, commonly referred to as XMC)—have become focal points in assessing how quickly China can close the gap with international incumbents on HBM die, stacking, and packaging.

Thermal Simulation Challenges and Solutions in 3DIC AI Chip Design
As AI workloads push chips to deliver ever higher compute density, designers are increasingly turning to three‑dimensional integration (3DIC) to stack dies vertically and pack more functionality into limited footprints. While 3DIC architectures unlock significant performance and bandwidth advantages, they also introduce complex thermal behaviors that are far harder to predict and manage than in traditional 2D layouts.

An Attempt at Compiling a Memory+Compute Fusion Thematic Index – A Dual-Track Framework
Most AI investors talk about “compute” as if it were the whole story: GPUs, accelerators, chips, cores. But every one of those cores needs somewhere to read from and write to. Memory and storage define how wide the data highway really is. In practice, AI performance is a fusion of compute and memory, not a solo act. So why do so many indices and ETFs separate them into different silos—one for semiconductors, one for memory, one for data centers—when the actual workloads keep blending them?

Surging Demand for Laser Drilling and Plasma Dicing Equipment in Advanced Packaging
Advanced packaging has become one of the semiconductor industry’s most important growth engines, and it is now pulling a surprising set of process tools into the spotlight. Among the most in-demand are laser drilling and plasma dicing equipment. These machines sit close to the heart of heterogeneous integration, fan-out packaging, wafer thinning, TSV formation, glass substrate processing, and other advanced flows where precision, yield, and throughput matter enormously. As packaging moves from a back-end afterthought to a strategic platform, the equipment used to shape, open, and separate materials has become just as important as the dies themselves.

D2D Interface Bandwidth and Latency Comparison in Chiplet Architectures
Chiplet architecture has turned the package into a real performance battleground. Once multiple dies are placed side by side or stacked within the same advanced package, the quality of the die-to-die, or D2D, interface becomes one of the most important determinants of system behavior. Bandwidth is no longer a nice-to-have metric, and latency is no longer a small implementation detail. Together, they shape whether a chiplet system feels nearly monolithic or frustratingly fragmented.

Stock Selection Logic and Alpha Validation of ESG-Themed Semi ETFs
Semiconductor themed ETFs are no longer just about growth and cycles. A growing subset now layers environmental, social, and governance (ESG) criteria on top of traditional sector exposure. These ESG semi ETFs promise two things at once: access to one of the market’s most powerful secular themes, and alignment with sustainability and governance standards. The pitch is appealing, but it raises two hard questions. First, how exactly are these stocks being selected? Second, does the ESG overlay help, hurt, or leave alpha unchanged?